Every organization says it needs high availability. Very few define what that means in hours and minutes. Availability is measured in nines. The gap between each level looks small on paper and feels large in practice:
| Availability | Downtime per year (approx.) |
| 99% | 3.65 days |
| 99.9% | 8.8 Hours |
| 99.99% | 53 minutes |
| 99.999% | 5 minutes |
Each extra nine costs more to engineer and more to run. The right target depends on what an hour offline costs your business: lost transactions, idle teams, regulatory exposure, and customer trust.
Design sets the ceiling for uptime. Operations decide how close you get to it.
Uptime is earned every hour
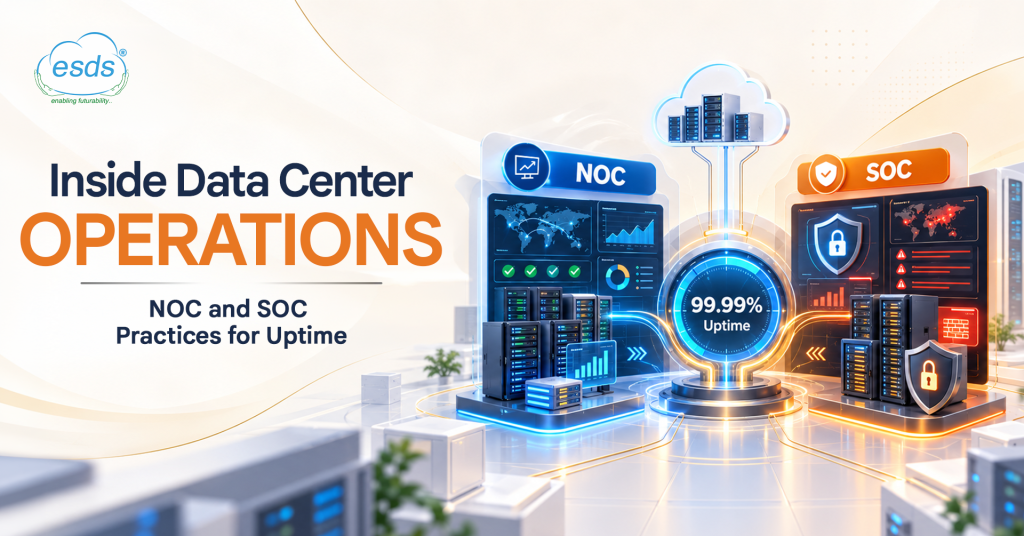
Data center uptime depends less on hardware alone and more on how people operate it. In modern data center operations, two teams carry that responsibility around the clock: the Network Operations Center (NOC) and the Security Operations Center (SOC).
In this blog, you will learn:
- Where NOC and SOC responsibilities overlap, and why they work best as partners
- The operational practices that protect data center uptime
- How ESDS approaches 24×7 data center operations
NOC: keeping infrastructure running
NOC is the operational heartbeat of a facility. Its job is availability and performance: keeping servers, storage, network links, power and cooling systems healthy every minute of the day.
A typical NOC team works across:
- Real-time data center monitoring of bandwidth, latency, packet loss, server health, temperature and power draw
- Alert triage, separating genuine faults from noise and routing each issue to the right engineer
- Incident response for hardware failures, link outages and capacity bottlenecks
- Capacity planning, using performance trends to forecast when racks, power or bandwidth will run short
- Change and maintenance windows, coordinated so that upgrades do not interrupt live workloads
SOC: keeping infrastructure trusted
If the NOC keeps the lights on, the SOC makes sure no one unwelcome walks through the door. Its focus is threat detection, investigation, and response across networks, applications, databases, and user access.
Core SOC functions include:
- Security event monitoring through SIEM platforms that collect and correlate logs from across the environment
- Threat detection mapped to known attacker techniques, using frameworks such as MITRE ATT&CK
- Privileged access and database activity oversight, since insider misuse is as real a risk as external attack
- Incident response and forensics, following a structured lifecycle: detect, contain, eradicate, recover and learn
- Regulatory reporting, which in India carries a hard deadline
Under the CERT-In Directions of April 2022, data centres and service providers must report specified cyber incidents to CERT-In within six hours of noticing them. A SOC that cannot detect and document quickly is a compliance risk as well as a security one.
Where NOC and SOC actually meet?
The NOC & SOC split is useful, but real incidents do not respect org charts. A sudden traffic spike might be a marketing campaign or a DDoS attack. A server slowing down might be a failing disk or cryptomining malware. The team that sees the symptom is not always the team that owns the cause.
| NOC | SOC | |
| Core question | Is it running? | Is it safe? |
| Watches | Performance, capacity, power, connectivity | Threats, access, anomalies, compliance |
| Responds to | Outages, hardware faults, bottlenecks | Intrusions, breaches, policy violations |
The most resilient data center operations treat the two as partners. Shared dashboards, joint escalation paths, and common incident tickets mean neither team works blind.
Practices that protect data center uptime
Technology helps, but the right approach keeps the data center running without interruptions. These practices separate strong operations from average ones.
- Runbooks for every known failure. Documented, tested procedures remove guesswork at 3 a.m. They also directly address the procedural failures that drive so many human-error outages.
- Clean shift handovers. In a 24×7 rotation, open issues, pending changes, and watch items must pass from one shift to the next without gaps.
- Alert hygiene. Too many alerts train people to ignore them. Tune thresholds, suppress duplicates, and keep every alert actionable.
- Unified visibility. One view across infrastructure, applications, and security shortens the time from symptom to root cause.
- Blameless post-incident reviews. Every incident should leave behind a fix, an updated runbook or a better alert, not a scapegoat.
- Drills and DR testing. Failover plans that are never rehearsed tend to fail when they are needed most.
- Synchronised time and retained logs. Accurate timestamps across systems make forensics and regulatory reporting possible.
How ESDS approach data center operations?
At ESDS, round-the-clock operations are built into the service model rather than added later. The ESDS Data Center and Cloud Migration approach ends in an “Operate” stage, where workloads are monitored, optimised, and scaled under 24×7 managed operations.
- One partner across the stack. ESDS takes ownership of infrastructure, OS, database, security and DR under a single SLA. This reduces the hand-offs that slow incident response.
- Centralised visibility. For organisations moving from hybrid or multi-cloud estates, ESDS focuses on consolidating tools and centralising operations, giving NOC teams one view instead of many.
- Real-time performance monitoring. Observability and AIOps platforms such as SWARAJ Garuda and SWARAJ Bodhi support data center monitoring from application to infrastructure.
- Security operations coverage. Managed Security Services work alongside SWARAJ Hansa (SIEM), SWARAJ Jatayoo (DAM) and SWARAJ Nandi (PAM) to support SOC functions.
- DR from Day 1. Disaster recovery is configured during the build phase, so resilience is in place before go-live.
- Compliance alignment. Operations are designed to align with MeitY, RBI, IRDAI, and DPDP requirements, with data residency kept within India.
Migration itself follows a parallel-run approach designed to minimise disruption during cutover.
Conclusion
Data center uptime is not a feature you buy once. It is the outcome of thousands of small, correct decisions made every hour by people who know what to watch and how to act. The NOC keeps infrastructure running. The SOC keeps it trusted. Together, backed by sound process and unified data center monitoring, they turn availability from a promise into a practice.
Planning to modernise your infrastructure with managed 24×7 operations? – Talk to an ESDS expert.
FAQs
- What is the difference between a NOC and a SOC?
A NOC keeps infrastructure available and performing, while a SOC keeps it secure from threats.
- Why do data center operations need to run 24×7?
Faults and cyber threats do not keep business hours, so monitoring and response cannot either.
- What does data center monitoring cover?
It tracks network, server, power, cooling and security signals in real time to catch issues early.
- What causes most data center outages?
Power failures and human error, often from procedures not being followed, are among the most common causes.
- How quickly must cyber incidents be reported in India?
Under CERT-In Directions, data centres must report specified incidents within six hours of noticing them.
Recent Comments